Weights on the GPU, libraries in RAM — held once. Native Linux system software that holds identical model weights once per GPU and identical shared libraries once in RAM, while every workload keeps its own isolated instance. Measured by the kernel, fully reversible, bit-identical results. Gewichte auf der GPU, Bibliotheken im RAM — einmal gehalten. Native Linux-Systemsoftware, die identische Modellgewichte einmal je GPU und identische Shared Libraries einmal im RAM hält, während jede Workload ihre eigene isolierte Instanz behält. Vom Kernel gemessen, vollständig reversibel, bit-identische Ergebnisse.
Sessions start about 30 % faster — the libraries are already in memory — and keep working near their memory limit. Sessions starten rund 30 % schneller — die Bibliotheken liegen bereits im Speicher — und arbeiten auch nahe am Memory-Limit weiter.
Up to 3.9× KV-cache capacity and five instead of three model instances per GPU; 36 % less RAM per AI session. Bis zu 3,9× KV-Cache-Kapazität und fünf statt drei Modellinstanzen je GPU; 36 % weniger RAM je AI-Session.
Identical model weights once per GPU, identical libraries once in RAM — every instance stays isolated. Identische Modellgewichte einmal je GPU, identische Bibliotheken einmal im RAM — jede Instanz bleibt isoliert.
Duplicate model weights and shared libraries collapse into one memory footprint — on the GPU and in RAM.Doppelte Modellgewichte und Shared Libraries fallen zu einem Speicher-Footprint zusammen — auf der GPU und im RAM.
On a shared AI server the same bytes sit in memory many times: the same model weights in every dedicated instance on a GPU, the same shared libraries in every environment in RAM. nexives recognises byte-identical content and holds it once — read-only, integrity-checked, reversible — while every workload keeps its own process, endpoint and working memory. Auf einem gemeinsam genutzten AI-Server liegen dieselben Bytes vielfach im Speicher: dieselben Modellgewichte in jeder dedizierten Instanz auf einer GPU, dieselben Shared Libraries in jeder Umgebung im RAM. nexives erkennt byte-identische Inhalte und hält sie einmal — nur lesend, integritätsgeprüft, reversibel — während jede Workload ihren eigenen Prozess, Endpoint und Arbeitsspeicher behält.
GPU: the identical weights of several model instances are held once per GPU; the freed memory becomes KV cache and room for more instances. RAM: the identical shared libraries of many environments and images are held once per node. Both measured by the kernel, both fully reversible. GPU: Die identischen Gewichte mehrerer Modellinstanzen werden einmal je GPU gehalten; der freie Speicher wird zu KV-Cache und Platz für weitere Instanzen. RAM: Die identischen Shared Libraries vieler Umgebungen und Images werden einmal je Node gehalten. Beides vom Kernel gemessen, beides vollständig reversibel.
Each instance keeps its own process, endpoint and KV cache; datasets, Python objects and application code are never shared. No change to models, images or the API — one restart of the workloads after installation is all it takes. Linux only. Jede Instanz behält ihren eigenen Prozess, Endpoint und KV-Cache; Datensätze, Python-Objekte und Anwendungscode werden nie geteilt. Keine Änderung an Modellen, Images oder API — ein Neustart der Workloads nach der Installation genügt. Linux-only.
Teams running several isolated instances of the same model per GPU — GPU clouds, model hosting, AI platform teams, unified-memory systems — and shared AI or data-science servers where many users keep their own environments. Teams, die mehrere isolierte Instanzen desselben Modells je GPU betreiben — GPU-Clouds, Model-Hosting, AI-Plattformteams, Unified-Memory-Systeme — sowie gemeinsame AI- oder Data-Science-Server, auf denen viele Nutzer eigene Umgebungen halten.
The Nexives scope is isolated, explicit, and easy to understand.Der Nexives-Bereich ist isoliert, explizit und leicht verständlich.
Multiple isolated workloads reference the same shared copy — without changing model results.Mehrere isolierte Workloads referenzieren dieselbe gemeinsame Kopie — ohne die Modellergebnisse zu verändern.
nexives is operated from the cockpit (NEXIVES Control Plane), a web page inside your own network. Every server is assessed before anything is installed, and every figure is measured afterwards and shown per server. nexives wird aus dem Cockpit (NEXIVES Control Plane) bedient, einer Webseite im eigenen Netzwerk. Jeder Server wird geprüft, bevor etwas installiert wird, und jede Zahl wird danach gemessen und je Server ausgewiesen.
The cockpit assesses each server over SSH: hardware, Kubernetes, GPUs, model servers, active workloads — and predicts what nexives would free. In the 40-user test the prediction reached 90 % of the measured result. Das Cockpit prüft jeden Server per SSH: Hardware, Kubernetes, GPUs, Modellserver, aktive Workloads — und sagt vorher, was nexives freigeben würde. Im 40-Nutzer-Test traf die Vorhersage 90 % des gemessenen Werts.
Installed from the cockpit — no image rebuilds, no application changes. Identical files are verified byte for byte before anything is shared; nothing is assumed from a file name or a version string. Aus dem Cockpit installiert — keine neuen Images, keine Änderung an Anwendungen. Identische Dateien werden Byte für Byte verifiziert, bevor etwas geteilt wird; nichts wird aus Dateiname oder Versionsnummer geschlossen.
After one restart of the workloads, identical model weights are held once per GPU and identical libraries once in RAM. Every instance keeps its own process, endpoint and KV cache. Any shared file can be returned to a private copy at any time. Nach einem Neustart der Workloads liegen identische Modellgewichte einmal je GPU und identische Bibliotheken einmal im RAM. Jede Instanz behält ihren eigenen Prozess, Endpoint und KV-Cache. Jede geteilte Datei kann jederzeit wieder zur privaten Kopie werden.
RAM freed, page cache freed, GPU memory and capacity per server — measured, not estimated, and shown in the cockpit. Where the system already shares, nexives reports nothing to reclaim. Freier RAM, freier Page Cache, GPU-Speicher und Kapazität je Server — gemessen, nicht geschätzt, und im Cockpit ausgewiesen. Wo das System bereits teilt, meldet nexives nichts zu holen.
Wherever several isolated instances load the same weights or the same libraries, nexives turns duplicate memory into capacity. The economics scale with the number of instances per GPU and environments per node. Überall, wo mehrere isolierte Instanzen dieselben Gewichte oder dieselben Bibliotheken laden, macht nexives aus doppeltem Speicher Kapazität. Die Ökonomie skaliert mit der Zahl der Instanzen je GPU und der Umgebungen je Node.
Each customer gets an isolated, SLA-backed instance of the same open model; the weights are held once per GPU. Measured on an NVIDIA T4 with vLLM: five instead of three instances on one card, 3.9× the KV-cache capacity — same requests, same answers. Jeder Kunde erhält eine isolierte Instanz desselben offenen Modells mit SLA; die Gewichte liegen einmal je GPU. Gemessen auf einer NVIDIA T4 mit vLLM: fünf statt drei Instanzen auf einer Karte, 3,9× KV-Cache-Kapazität — gleiche Anfragen, gleiche Antworten.
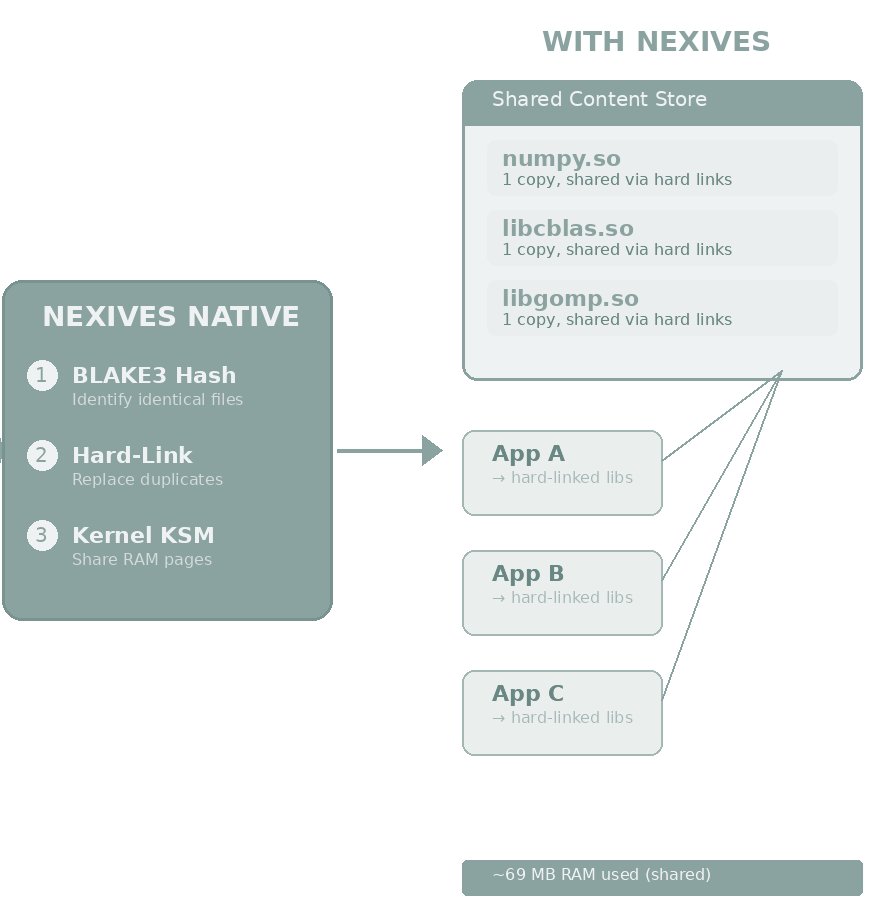
JupyterHub, research labs, enterprise data-science platforms. Forty users with their own PyTorch environments needed 36 % less RAM per session, started about 30 % faster and kept working near their memory limit — 92 % of the work done where private copies managed 14 %. JupyterHub, Forschungslabore, Data-Science-Plattformen im Unternehmen. Vierzig Nutzer mit eigenen PyTorch-Umgebungen brauchten 36 % weniger RAM je Session, starteten rund 30 % schneller und arbeiteten nahe am Memory-Limit weiter — 92 % der Arbeit erledigt, wo private Kopien auf 14 % kamen.
On NVIDIA GB10 / Grace-class systems the shared weights free system memory directly: +90 % KV cache for three 7B instances, 30.5 GB freed. On Kubernetes with many different ML images, the memory charged per pod falls and requests can be sized from measured usage. Auf Systemen der Klasse NVIDIA GB10 / Grace geben die geteilten Gewichte direkt Systemspeicher frei: +90 % KV-Cache für drei 7B-Instanzen, 30,5 GB frei. Auf Kubernetes mit vielen verschiedenen ML-Images sinkt der je Pod angerechnete Speicher, und Requests lassen sich nach gemessener Nutzung bemessen.
Where the system already shares — replicas of one container image, servers with a single environment, conventional web hosting — nexives finds little to hold once, and reports it as such rather than estimating. Wo das System bereits teilt — Replikate eines Container-Images, Server mit einer einzigen Umgebung, klassisches Web-Hosting — findet nexives wenig, das es einmal halten könnte, und weist genau das aus, statt zu schätzen.
Nexives was founded in 2026 by two partners with complementary backgrounds: systems engineering and infrastructure operations on one side, venture building and commercial strategy on the other. The company develops software at the operating-system level for dense AI workloads on Linux. Nexives wurde 2026 von zwei Partnern mit komplementären Hintergründen gegründet: Systemtechnik und Infrastrukturbetrieb auf der einen Seite, Unternehmensaufbau und kommerzielle Strategie auf der anderen. Das Unternehmen entwickelt Software auf Betriebssystemebene für dichte AI-Workloads unter Linux.
Director of IT infrastructure and of cloud and virtualization computing at Liberty Global International; for the past seven years with ORS, Austria’s broadcasting services operator — today Big Blue Marble — where he is Group CIO. Founder and managing director of Finpin Technologies; at nexives he leads engineering. Leitete bei Liberty Global International die IT-Infrastruktur sowie Cloud und Virtualisierung; seit sieben Jahren bei ORS, dem österreichischen Rundfunk-Dienstleister – heute Big Blue Marble –, dort Group CIO. Gründer und Geschäftsführer der Finpin Technologies GmbH; bei nexives führt er die Technik.
LinkedIn ↗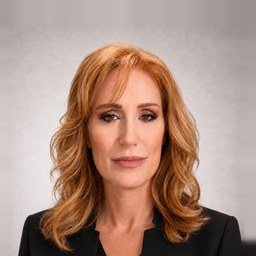
For more than two decades, Amelie Clement has worked where technology, markets and entrepreneurial ambition converge. As founder, CEO and strategic advisor, she has built ventures in AI, software and interactive entertainment, structured international partnerships and transactions, and led growth initiatives from start-up to Fortune 500. Seit mehr als zwei Jahrzehnten arbeitet Amelie Clement dort, wo Technologie, Markt und unternehmerischer Anspruch zusammenfinden. Als Gründerin, CEO und strategische Beraterin hat sie Unternehmen in den Bereichen KI, Software und Interactive Entertainment aufgebaut, internationale Partnerschaften und Transaktionen gestaltet und Wachstumsinitiativen vom Start-up bis zum Fortune-500-Konzern verantwortet.
LinkedIn ↗Nvidia guided for roughly 70 % growth two fiscal years out — and named memory supply, not demand, as the constraint. Nvidia stellt rund 70 % Wachstum für das übernächste Geschäftsjahr in Aussicht — und nennt das Speicherangebot, nicht die Nachfrage, als Grenze.
When memory is the scarce input, the density of each installed gigabyte stops being a tuning detail and becomes an economic variable. That is the margin nexives works with. Wenn Speicher der knappe Einsatzfaktor ist, ist die Dichte jedes installierten Gigabytes kein Feinjustierungsdetail mehr, sondern eine ökonomische Größe. Das ist der Spielraum, mit dem nexives arbeitet.
Nvidia Q2 FY27 results SourceQuelle ↗
Shared weights and libraries are byte-identical to the private copies — checksums are verified before anything is shared, sharing is fully reversible, and every instance sees the same bytes.Geteilte Gewichte und Bibliotheken sind byte-identisch mit den privaten Kopien — Prüfsummen werden vor dem Teilen verifiziert, das Teilen ist vollständig reversibel, und jede Instanz sieht dieselben Bytes.
Reach out for a read-only assessment of one of your nodes, a pilot on your own models and environments, or a partner conversation about the Provider Edition for GPU clouds and model hosting. Melden Sie sich für eine nur lesende Vorab-Prüfung eines Ihrer Nodes, einen Pilot auf Ihren eigenen Modellen und Umgebungen oder ein Partnergespräch zur Provider Edition für GPU-Clouds und Model-Hosting.
info@nexives.com